
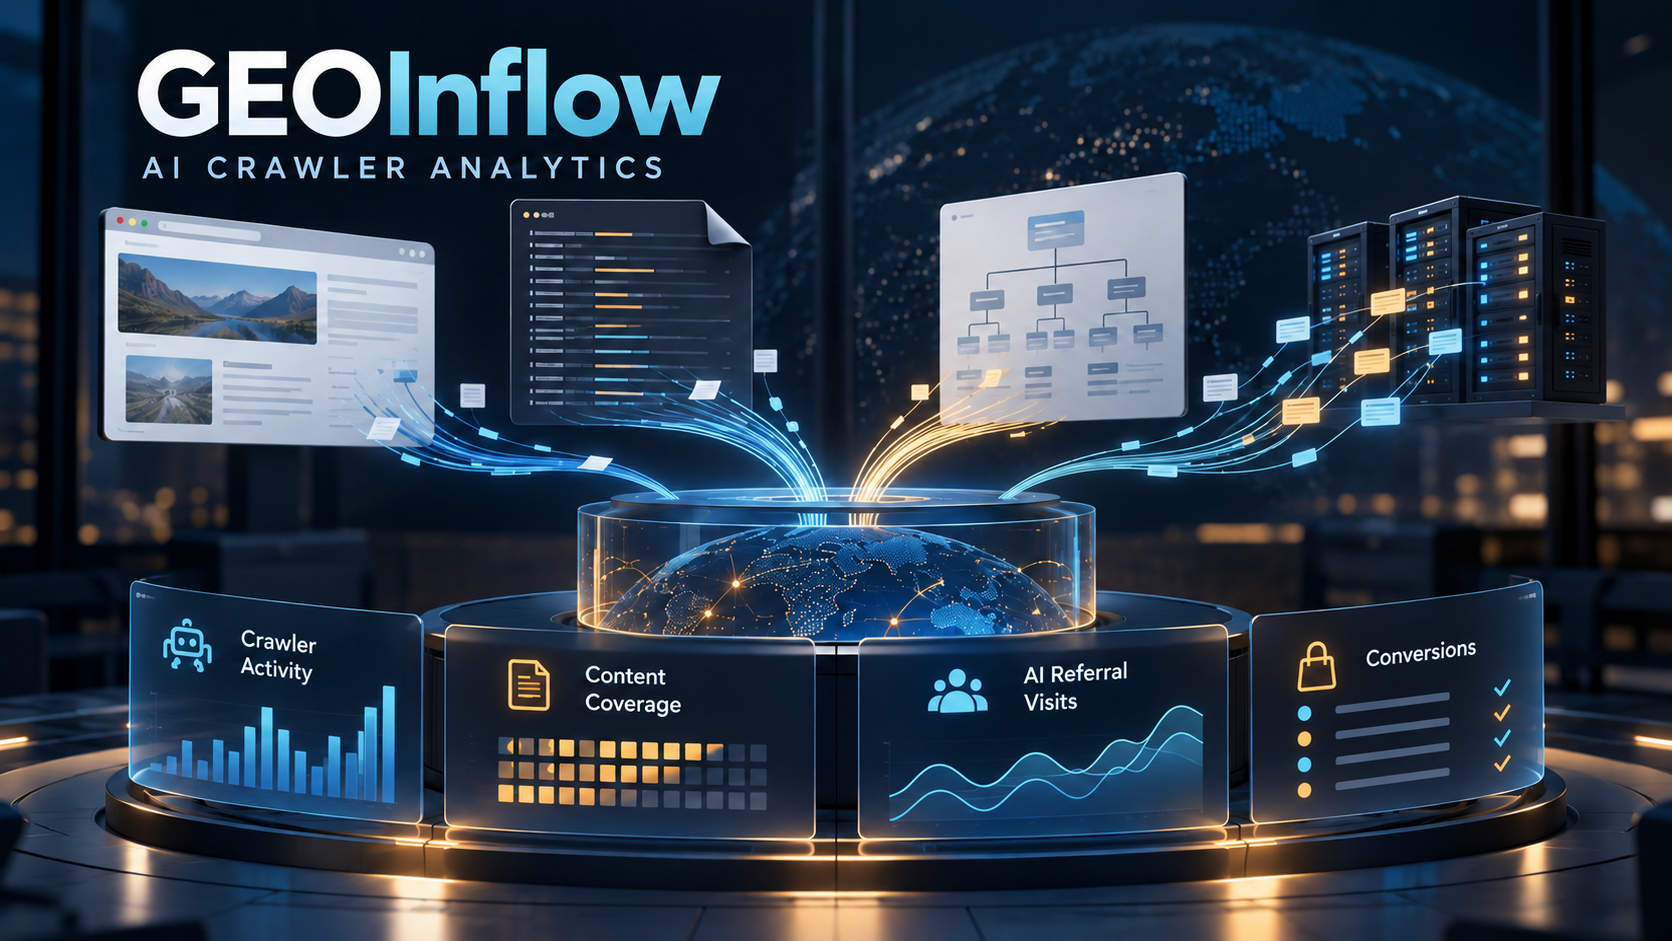
GEO teams use GEOInflow AI crawler analytics when they need one self-hosted view of website visitors, AI-search referrals, server crawl logs, content coverage, and conversions. The useful distinction is evidence: GEOInflow can show observed requests and visits, but those records do not by themselves prove indexing, model training, answer citations, rankings, or revenue impact.
Tool Summary
GEOInflow is an MIT-licensed, self-hosted website and AI crawler analytics application. Its repository describes a shared website context that connects four evidence sources: browser tracking, server or CDN request logs, sitemap or file-based content inventories, and configured business events. The current source version documented at the reviewed commit is v1.2.
This is not another prompt pack or an Agent Skill. It is a web application for operators who want to inspect which crawler identities request their pages, whether important URLs appear in the observed logs, where requests fail, which AI platforms send referral sessions, and whether those sessions complete configured goals.
Big Prompt Hub reviewed the public repository and documentation at commit fa2a8a6510583a3c9dbac3523167f3931fd715df. We did not deploy the stack, load-test it, or independently validate its identity-matching accuracy. Product behavior below is therefore repository-backed description, not a hands-on benchmark.
What GEOInflow Measures
The product is most useful when a team keeps four questions separate instead of rolling them into one vague “AI visibility” score.
- Crawler activity: which declared identities requested the site, which paths they touched, how often they returned, and what HTTP status, cache, latency, or response-size evidence was recorded.
- Content coverage: which pages in an imported sitemap, CSV, or JSON inventory have observed crawl records, which are repeatedly requested, and which remain blind spots within the available observation window.
- AI referral visits: which supported AI-search referrers sent browser sessions, which landing pages received them, and how those sessions moved through the site.
- Business outcomes: whether referred visitors completed goals or events the operator actually configured, with crawler requests, sessions, and conversions measured as separate things.
The repository’s crawler catalog covers named providers including OpenAI, Anthropic, Perplexity, Google, Microsoft, ByteDance, Baidu, Kimi, and Tencent Hunyuan. It distinguishes platform, product, request identity, and purpose. That matters because a training crawler, a search crawler, and a user-triggered fetch can belong to the same provider while representing different activity.
How the Data Fits Together
| Input | What it contributes | What it cannot establish alone |
|---|---|---|
| Browser tracking | Pageviews, referral sessions, landing pages, events, goals, and conversions | Crawler activity that never executes JavaScript |
| Server or CDN logs | Requested URLs, timestamps, declared user agents, response codes, cache and latency fields | Whether an answer cited the page or a human clicked a recommendation |
| Content inventory | A known page set for coverage and missing-observation checks | Whether a missing record means the page was never indexed elsewhere |
The combined view is the product’s clearest advantage. Browser-only analytics usually cannot see bots that never run the script. Raw logs can show requests but not a visitor’s later goal completion. A content inventory supplies the denominator needed to discuss coverage rather than merely listing popular paths.
GEOInflow also records evidence quality. A user-agent string is only a declaration and can be copied. Where supported, official IP ranges, DNS checks, or trusted edge evidence are stored separately; historical records without adequate proof remain unknown instead of being silently promoted to verified crawler traffic.
Setup / Working Method
The repository documents a Docker-based quick deployment. From the source root, the starting command is:
sh scripts/liekan-deploy.shThe script is documented to generate a private environment file and random secrets, build images, run migrations, and start the application, log worker, analytics worker, PostgreSQL, and Redis. A fresh installation uses the initial account admin with password liekan; the repository explicitly instructs operators to change that password after signing in. Production use also needs a domain, HTTPS, a trusted reverse proxy, backups, and the deployment-specific checks described in the project documentation.
1. Connect browser visits
Create a website record, then add the generated browser script to the site template. Basic pageview collection can start there, but identity-sensitive visitor metrics depend on correct proxy and ingress evidence. Heatmaps, recordings, performance data, and custom events have their own inputs and should not be assumed from the basic tag.
2. Connect crawler logs
Choose manual Nginx, Apache, or JSON import for an initial review, or configure a continuous server or supported Cloudflare source. The documented workflow previews fields and rejection reasons before analysis. Treat log ownership, retention, IP handling, provider permissions, and ingestion secrets as deployment decisions rather than copy-and-paste details.
3. Import the real page inventory
Import a sitemap urlset, CSV, or JSON file containing the pages that actually matter. Coverage results only mean something relative to that set. If the inventory covers one section rather than the whole site, keep that limitation visible when reviewing blind spots.
4. Review one evidence chain at a time
Start with one crawler identity and a fixed date range. Check source continuity, verification status, requested pages, responses, and content coverage. Only then compare AI-referral landing pages and configured goals. This order prevents a crawler request from being misreported as a referral visit or a conversion.
Best Fit Users
- Company and content-site operators: need crawler, referral, and conversion evidence under their own infrastructure and permissions.
- Publishers and media teams: need to see which sections receive repeated automated requests and whether that activity returns human visits.
- Developer-documentation teams: need page-level crawl coverage, response evidence, and content-inventory comparisons.
- GEO consultants managing several sites: need repeatable evidence scopes and exports without pretending that one metric proves AI-search performance.
Comparison / Limits
- A crawler request is not an answer citation. Logs show observed access. Citation monitoring requires separate answer evidence.
- A user-agent match is not source proof. Review IP-range, DNS, or trusted-edge evidence where the catalog supports it; otherwise retain the unknown state.
- A referral session is not the same as a crawl. Browser referrers, server requests, and goal completions have different units and coverage limits.
- No observed request is not always a confirmed zero. First confirm that the log source was continuous and the page inventory and date window were complete.
- GEO Weight is a beta indicator. The project defines it around qualified AI content access over the most recent 30 complete calendar days. It is not a ranking, citation, training, or revenue score.
That restraint is important. The nearest Big Prompt Hub companion, GEO SEO Claude Code Skill Collection, helps teams audit crawler access, citability, schema, and AI-search readiness. GEOInflow covers a different layer: ongoing observation from site-owned visits, logs, inventories, and goals.
Use Cases
- Find crawler blind spots: compare an imported set of priority pages with observed requests during a complete logging window.
- Investigate access failures: inspect status codes, cache fields, latency, source continuity, and affected paths before changing robots or server policy.
- Separate activity from business return: compare crawler requests with AI-referral landing pages and configured conversions without treating correlation as causation.
- Document a GEO operating review: export a fixed date, timezone, identity filter, and evidence state so another reviewer can reproduce the scope.
Limitations
- Self-hosting is an operations commitment: the stack includes an application, workers, PostgreSQL, Redis, HTTPS, proxy configuration, backups, and upgrade work.
- Data quality depends on connected sources: missing browser tracking, incomplete logs, partial inventories, or unconfigured goals remove the corresponding conclusions.
- Provider controls vary: Cloudflare features depend on the actual account plan, permissions, Zone configuration, and available fields.
- The repository is new: evaluate the fixed commit, migration and backup procedures, issue history, and future releases before using it with production analytics data.
- This review is documentation-based: Big Prompt Hub has not measured performance, accuracy, capacity, or operational reliability.
Common Mistakes & Fixes
- Calling every declared bot verified: filter by evidence state and preserve unknown records instead of relabeling them.
- Reading crawler volume as GEO success: add separate citation, referral, and conversion evidence before making outcome claims.
- Importing an incomplete sitemap as the whole site: state the inventory boundary and update it before comparing coverage periods.
- Leaving the initial password unchanged: replace it immediately, then configure production HTTPS, proxy trust, secrets, permissions, and backups.
- Making a policy change from one short window: keep the same identity and date definitions, record the intervention, and observe a comparable complete period.
Common Questions
- Q: What does GEOInflow AI crawler analytics track?
A: It combines browser visits, AI-search referrals, crawler logs, content inventories, and configured conversion goals inside a self-hosted application. - Q: Can GEOInflow track ChatGPT crawler visits?
A: It can classify supported OpenAI request identities from connected logs and preserve their verification state. A declared user agent alone does not prove the source. - Q: Does GEOInflow need an AI model API key?
A: The repository says core website analytics and crawler identification can run without one. Optional AI analysis is disabled by default and requires the operator to choose a model connection and data scope. - Q: How do I self-host GEOInflow?
A: The repository documents a Docker deployment script, followed by website creation, browser-script setup, crawler-log connection, and content-inventory import. Production use also needs HTTPS, proxy trust, backups, and secure credentials. - Q: Can GEOInflow prove that an AI answer cited my page?
A: No. It can record supported crawler and referral evidence, but model-answer citations require a separate monitoring source.
Need the project’s own walkthrough? Open the GEOInflow repository for its introduction video, quick start, deployment guide, and crawler-analysis documentation.
Follow @bigprompt, then explore AI Tools and Marketing & Growth.
Related Big Prompt Hub Pages
GPT Image 1 Migration: Move API Workflows to GPT Image 2.5
Travel Sketchbook Illustration Prompt: Hand-Drawn City Journal
Veo 3.1 Video Ad Prompt: Miniature Presenter Product Demo
huashu-motion Skill: Build Editable Product Launch Videos
Awesome Seedance Prompt Library: Turn Real Video Cases into a Skill
Big Prompt Hub Review
Start with GEOInflow when your team needs one self-hosted place to compare crawler requests, known content, referral sessions, and configured goals without collapsing them into a single visibility claim. Delay adoption if you cannot maintain PostgreSQL, Redis, workers, HTTPS, trusted ingress, backups, and source-quality checks. Keep the optional model-powered analysis for later; first prove that the browser, log, inventory, and goal inputs are complete enough to support the decisions you want to make.
Leave a Reply
You must be logged in to post a comment.